 HackerTube.runGood videos, with context.
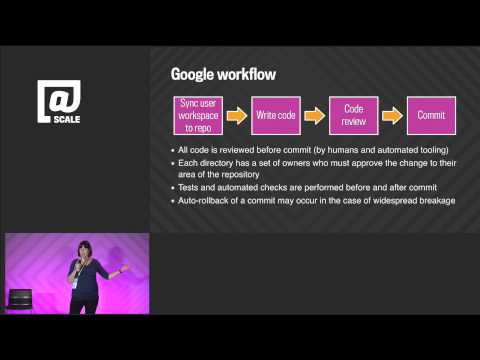
Why Google Stores Billions of Lines of Code in a Single Repository
About this video
Rachel Potvin describes the scale of Google's codebase and its custom monolithic source repository. She explains the reasons for the monorepo model, the tooling that makes it workable, and its tradeoffs.
Why it appears in the archive
The go-to reference in monorepo and trunk-based development discussions, recommended as a firsthand account of how Google manages source control.
AI-generated summary and labels from the source dataset; verify important details against the video. Source & credits.
From the Hacker News discussion
It's common practice for folks building Go binaries (but not libraries) to check in the code for their dependencies. So whenever you build Docker, you get the same thing unless Docker made a change (either by changing Docker itself or explicitly checking in an upgrade to a dep). There are a few nice things about it; vendoring means you won't have a dependency on other repos or archives being available, and if you're a binary maintainer you can see source changes in your own code and that of your dependencies side-by-side if you're, say, investigating a bug that came up between certain revisions. The not-so-nice things are pretty much what you'd think. There isn't a command to say "give me upgrades, but not ones that the author flagged as breaking changes". If you're writing a _library_ that is depended on by other _libraries_ there is no one conventional way to safely do breaking changes, so there's a lot of effort to avoid those changes plus sometimes hacks like different repo paths for different versions. Part of the history is that, internally, Google's got one version of third-party code in the latest rev of their source control tree, by company policy. You upgrade something for one, you upgrade it for the whole codebase. Sounds daunting, but they have lots of testing, canary servers, and so on to catch problems. There is a great talk about some of this by Rachel Potvin (can't recall if it covers the third_party/ stuff specifically): [VIDEO] So Go's initial model didn't c
Read original comment ↗Google doesn't use perforce anymore. They have a custom in-house SCM that has various interfaces wrapped around it. I'd recommend this video that describes it. [VIDEO]
Read original comment ↗Googler opinions are my own. I also highly recommend this ACM article talking about our source control from 2016. [LINK] There's also a YouTube video which is linked from the wired article that is good. [VIDEO]
Read original comment ↗Google gave a talk at the @scale conference in 2015 about this very topic. You can watch it here (30 minutes): [VIDEO]
Read original comment ↗What I don't understand is how they accomplish larger collaborative changes. The paper says: "Almost all development occurs at the 'head' of the repository, not on branches." Googler Rachel Potvin made an even stronger statement in her presentation about "The Motivation for a Monolithic Codebase" [1]: "Branching for development at Google is exceedingly rare [..]" In the related ACM paper she published with Josh Levenberg there is the statement that: "Development on branches is unusual and not well supported at Google, though branches are typically used for releases." I my world when we have to make a bigger change we create a branch and only merge it into the trunk when it is good enough to be integrated. The branch enables us to work on that change together. I don't understand how they do this at google. As far as I understand in their model they either have to - give up on collaboration and always have just a single developer work on a change. - share code by other means. - check in unfinished work to the trunk for collaboration and constantly break trunk. [1] [VIDEO] [2] [LINK]
Read original comment ↗This paper from last year surveys Google “engineers who have experience with both monolithic repos and multiple, per-project repos” to see what exactly they like and dislike about monorepos. The results match my experience, and I find the paper well-written (especially like the “Threats to Validity” section that says what biases may have affected the results; more papers and arguments should have them IMO). Older reading on monorepos that I'm aware of: • Dan Luu, Advantages of monorepos (2015) [LINK] • Why Google Stores Billions of Lines of Code in a Single Repository (2015): [LINK] (HTML) / [LINK] (PDF) / [VIDEO] (video) This paper is from the “Software Engineering in Practice” track of the ICSE 2018 conference: • [LINK]
Read original comment ↗